Lab
When semantic search finds a precedent that never existed
Short answer
A false precedent is a retrieved memory that looks like the current situation without really concerning it. Semantic search produces them because closeness in meaning is not the same as identity. Found does not mean true: you need to be able to judge provenance, date and context, and accept that the right answer is sometimes "no convincing precedent".
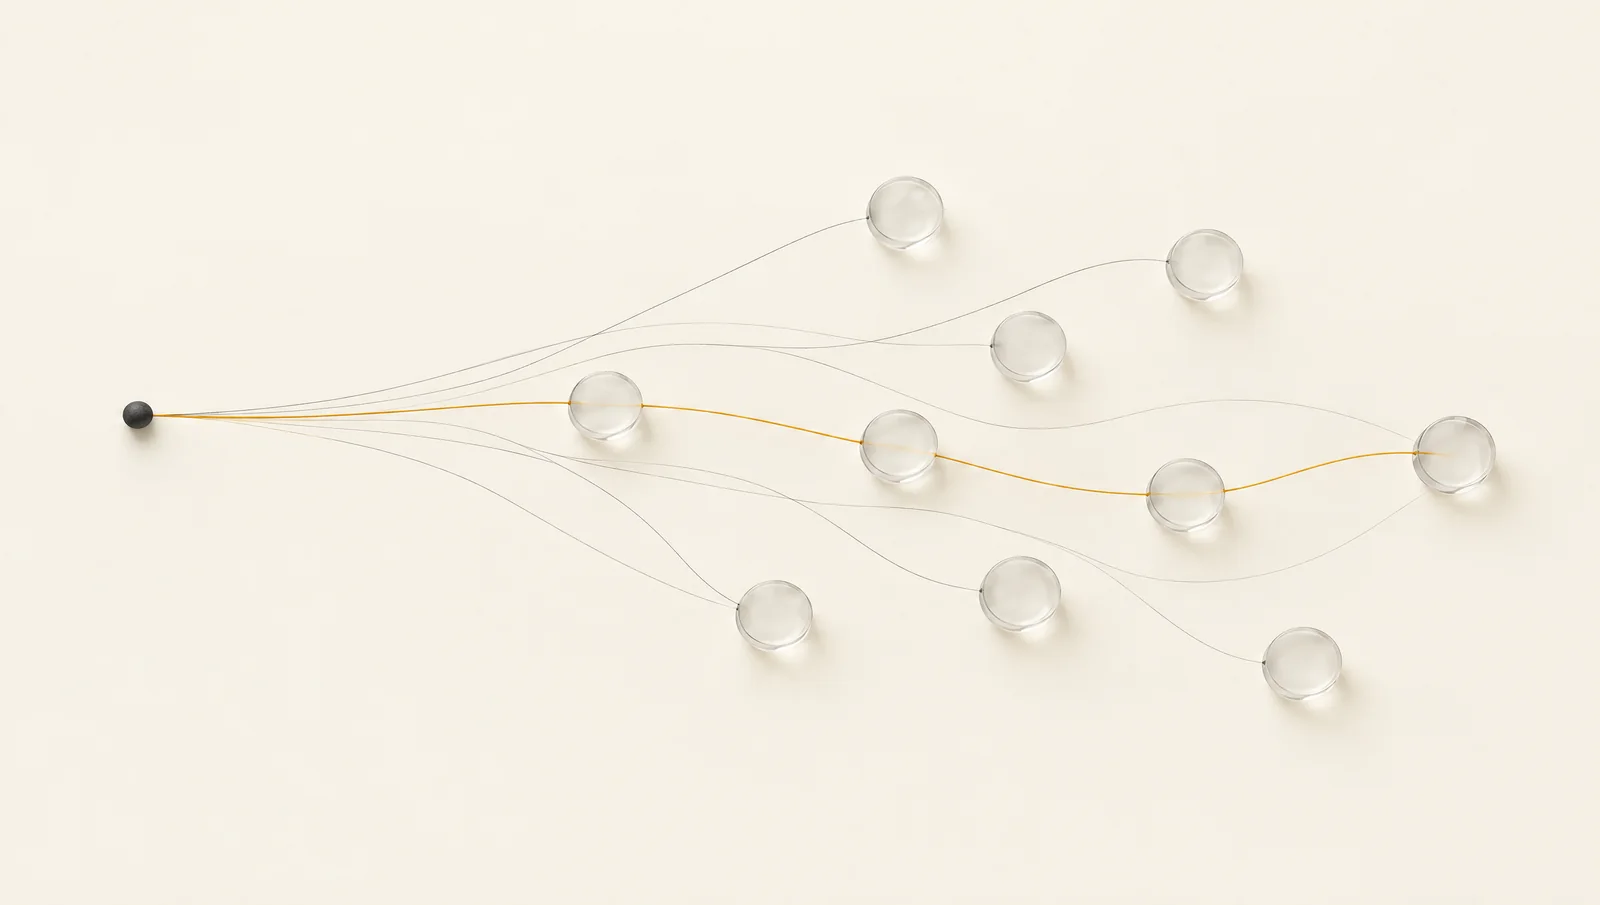
You ask an AI: “Did we already settle this question?” It answers yes, back in March, and quotes the decision made at the time. It is precise, dated and plausible. It may also be wrong: the March decision was about something else that looked a lot like it.
This is one of the trickiest problems for any memory meant to retrieve context. It gets little attention because it is less dramatic than forgetting. It is also more dangerous.
What semantic search does, and why it is useful
Semantic search looks for texts whose meaning is close to the question, rather than texts that contain the same words. If you type “subcontracting agreement” and it brings back a note titled “deal with the vendor”, it did its job.
That is valuable, because nobody remembers the exact words they used six months ago. A keyword search makes you guess your own past vocabulary. Semantic search spares you that effort.
It is not always necessary. For a few dozen well-organized notes, an up-to-date document and the search function of your usual tool work perfectly well. The problem shows up when the history grows, when several people or several AI tools write into it, and when topics resemble one another. What degrades as volume grows is described in limits of retrieval at scale.
How a false precedent gets made
A false precedent is a retrieved memory that looks like the current situation but does not concern it: different subject, different period, different constraint. A few general reasons explain it.
First, closeness in meaning is not identity. Two decisions about a budget both talk about budgets without having anything to do with each other. Second, the vocabulary of a trade is repetitive: inside one company, many topics look alike by construction. Third, an old, outdated memory stays just as close to the question as a memory that is still valid, unless something signals that it has been replaced.
Imagine a small product team. In February, it rules out an invoicing tool for its pilot: too expensive for about twenty test customers. In September, it wonders whether it could adopt one for the public launch. The search brings back the February decision: “already ruled out”. But the reason back then, the cost for a pilot, no longer holds for a launch. And the tool under consideration may not be the same one. The team could have given up a good option on the strength of a memory that was not about it.
Why a false precedent is worse than forgetting
When information is missing, you know it. You look elsewhere, ask a colleague, or start from scratch with your eyes open.
A false precedent, on the other hand, looks like evidence. It has a date, a wording, sometimes a name. The AI that receives it will tend to use it, and to present it with confidence, because that is what it was given. The risk is building a whole line of reasoning on a base that does not hold, without anyone noticing.
That is why, in a memory meant to retrieve context, saying “I have nothing convincing” is better than bringing back something at any cost. We come back to this in an article on why we deliberately test topics that do not exist.
Found does not mean true
First principle: what a memory retrieves is a working lead, not a truth. To judge it, you need to know where it comes from, when it was written, in what setting, and whether something has replaced it since. Nawame keeps the provenance, timing and context of memories for this reason. We covered the other side of the problem in the article on what happens when a decision changes. The same principle, seen from the angle of how far to trust a memory, is developed in why found does not mean true.
Second principle: the answer must state how certain it is. Nawame uses three public wordings:
- Precedent found: a memory answers the described situation well.
- Possible connection: something looks similar, to be checked before relying on it.
- No convincing precedent: nothing convincing was found, and that is said plainly.
We do not detail here how Nawame tells these three cases apart: that is part of our technology. What matters to you is what you see and what you do with it. The third case is the most underrated. A memory that can answer “nothing convincing” is more useful in the long run than one that always has an answer. It is the retrieval-side counterpart of what we said about writing: not writing is a feature.
What this changes for you
You do not need to understand the mechanics to take away a few simple habits.
- Check the date and the provenance before relying on a precedent, especially an old one.
- Ask what differs. A good question to put to the AI: “How does the situation back then differ from today’s?”
- Treat a possible connection as a hypothesis. It points you somewhere, it does not settle anything.
- Keep the decision. Nawame provides context. Judgment and decisions stay human.
This applies to Nawame as much as to any other memory, native or not. No system is immune to this kind of error, and the only serious defense is to make the error visible.
Current limits
Nawame does not eliminate false precedents. They are among the hard problems that the Lab studies and measures: false precedents, noise, context selection, timing.
In practice, the distinction between the three wordings can go wrong in both directions. An overly cautious memory can miss a real precedent and answer “no convincing precedent” when one existed. An overly confident memory can present as found what was only a connection. Both errors cost something, and each improvement on one side risks degrading the other. The types of errors and how to count them are described in how we measure memory errors.
We do not publish a numerical measurement on this point here. We would rather tell you the problem is open than show you a figure that gives an impression of mastery.
How to use it without trusting it blindly
If you work with an AI on topics that last, keep in mind that the most useful memory is not the one that retrieves the most, but the one whose answers you can check. The FAQ gives more detail on how Nawame keeps and returns context.
To try it with your own topics, Nawame is free up to 10 memories.