Lab
Limits of retrieval at scale
Short answer
As a collection grows, search returns more passages that are close without being right: near-duplicates, outdated versions, contradictions. Answers can get worse even though nothing changed in the system. Filtering (by project, period, status, permissions) and well-organized, dated content help more than simply adding data.
A team builds an assistant that answers from its internal documents. At first the collection is small, the answers are pretty good, and everyone is pleased. Two years later the collection has grown a lot and the answers have gotten blurrier. Nobody touched the system. The content itself changed character.
This is one of the most counterintuitive traps in information retrieval: adding data does not always improve the answers, and it can make them worse. This article walks through the mechanisms in plain terms, with no numbers and no inside details, and then covers what you can do on your side.
Recall and precision, in two pictures
Two words come up constantly. Recall is the share of everything relevant that the search managed to find. Precision is the share of what it returned that is actually relevant.
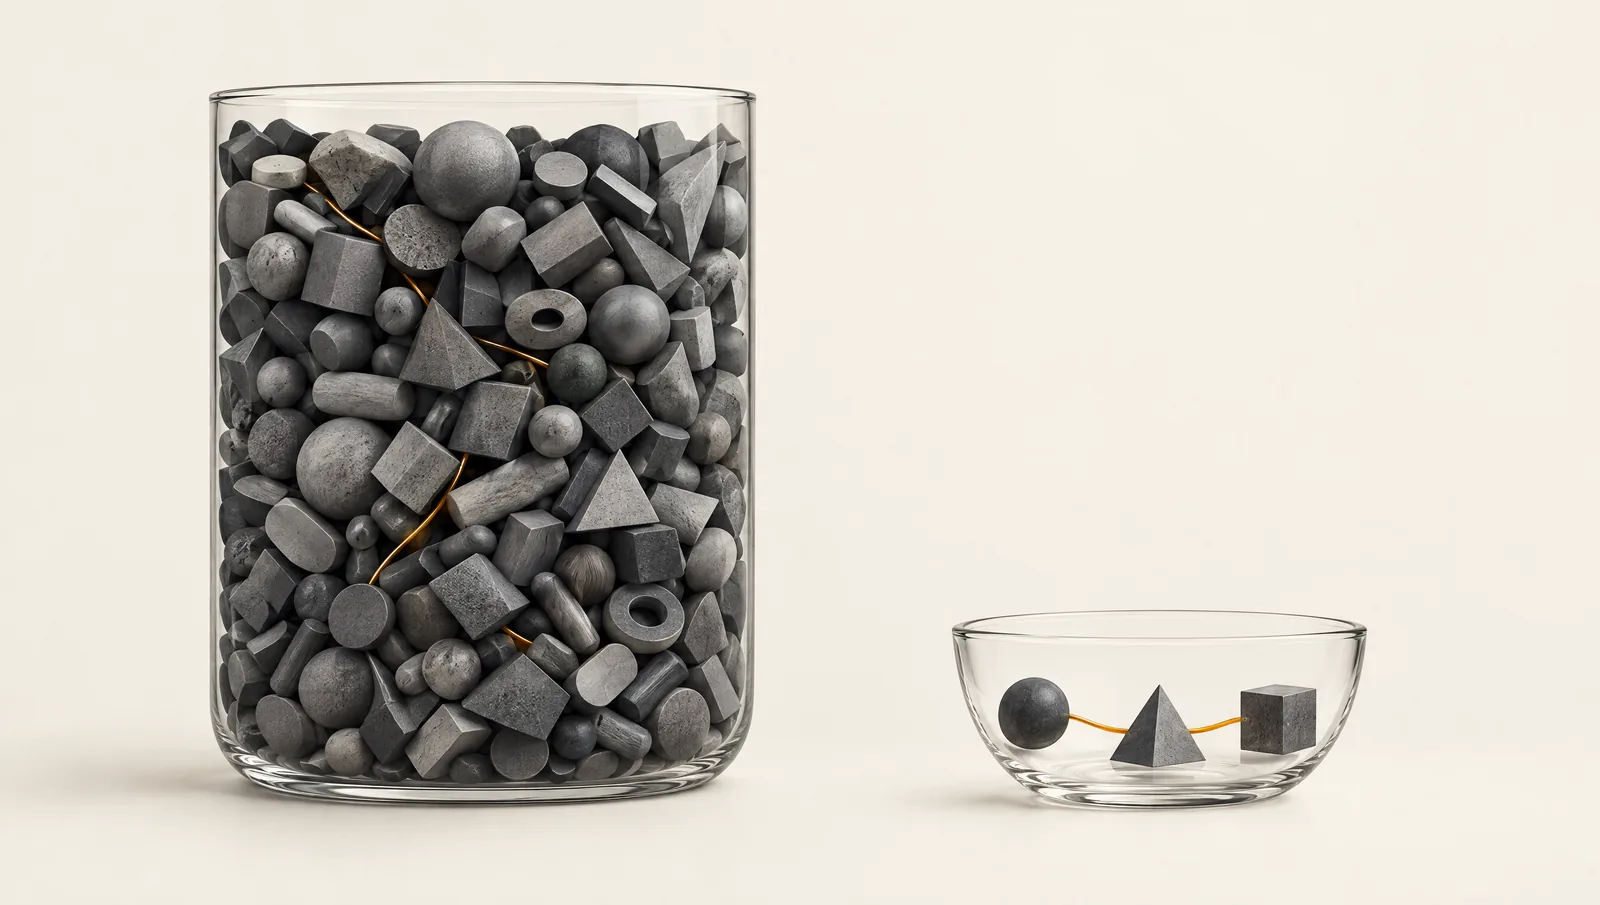
Picture two librarians. The first comes back with an armful of books: the right one is probably in there, but buried among the others (good recall, poor precision). The second comes back with a single book: if it is the right one, perfect, and if not you have nothing (high precision, fragile recall).
No setting delivers both perfectly. You pick a trade-off, and the size of the collection moves it: the more material there is, the harder it is to be complete and sharp at once.
Embeddings bring meanings close, not identities
An embedding is a numerical representation of a text, built so that texts with similar meanings end up near each other. That is what lets you search for “refund a customer” and land on “reimbursement procedure” even though the words differ.
But close in meaning is not the same as identical. “We are postponing the launch” and “we are keeping the launch date” are about the same thing and say the opposite. A negation, a date, a proper name or a version number counts for little in closeness of meaning, while it changes everything for you.
That is the mechanism behind the case we describe in the article on the false precedent in semantic search: two situations that look alike without being comparable.
Lexical, semantic, hybrid
Lexical search compares words. It is excellent for exact names, reference numbers, codes and rare terms. It is deaf to rephrasing: search for “cancel” when the document says “terminate” and it walks right past.
Semantic search compares meanings. It catches rephrasing, but it is less dependable for exact identifiers and fine shades of wording.
A hybrid search combines the two, and broadly speaking that is often a good idea. It does not make the problem disappear: someone still has to decide how to merge the two lists of results, and that adds its own errors. For the difference between retrieval, a vector database and a memory, see AI memory vs RAG.
Why more documents can mean worse answers
Four mechanisms work together as a collection grows.
Near-duplicates. A living collection piles up versions of the same document, copies, drafts. For a given question, the top results fill with almost identical passages, and the one different item that mattered gets pushed down where nobody reads it.
Noise. The more documents you have, the more passages look vaguely like any question you might ask. The odds of finding one that looks plausible and is wrong go up with volume.
Freshness. To a measure of closeness in meaning, a three-year-old text is as near to the question as yesterday’s. Unless the date is taken into account, nothing puts it behind.
Contradictions. Two versions of the same fact land side by side, and a model that receives both has no reliable way to know which one is current.
A fictional example. A support team has three things in its collection: the 2022 refund procedure, the 2024 one, and a draft of the next. The question “how do we refund an annual subscription?” returns three nearly identical passages, two of them outdated. The answer mixes up the steps. None of the three documents is wrong on its own. It is their coexistence that is wrong.
The same risk exists on the prompt side when you paste in too much material, and we cover it in giant prompt or targeted context.
Ranking, latency and cost: what grows with the collection
When search finds many candidates, order matters more than anything: only a few passages can be handed to the model, so whatever ranks below does not exist for it. Ranking is the step that decides that order, and answer quality leans on it heavily. How a given system ranks its results is exactly what sets systems apart, and at Nawame we do not publish that detail.
Latency and cost follow the same slope, broadly speaking: more content means more work to index it, keep it up to date and scan it. When a document changes, its index has to be rebuilt. Those costs are real, but they are not the most troublesome part. A slow system is noticed at once. A system that answers fast and wide of the mark is noticed much later.
Filtering changes everything
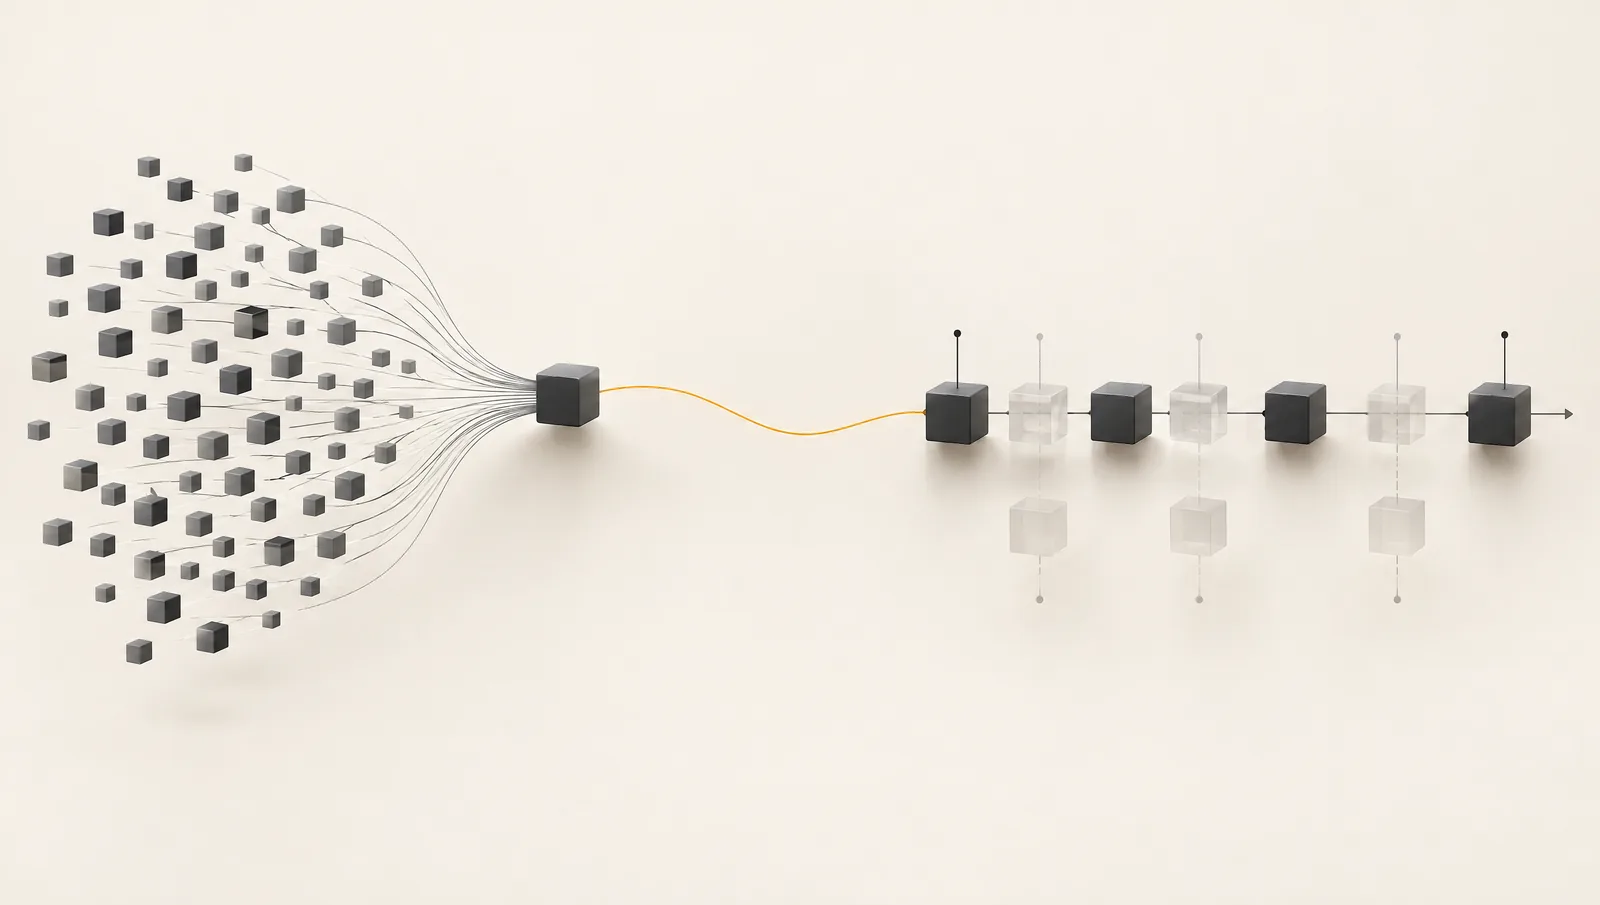
The most effective way to keep good answers on a large collection is to shrink the search area before searching by meaning. A filter removes thousands of candidates at once that should never have been competing:
- by project or client: you only search within the right scope;
- by period: you drop whatever predates a change;
- by status: you search only what is decided or established as a reference, not drafts;
- by permissions: you only search what the person is allowed to see.
The catch is that a filter needs labels. Someone has to have said which project a text belongs to, when it dates from, what its status is. Without that work, the filter has nothing to filter.
On the Nawame side, an AI only receives what Nawame is authorized to return for your account, and a key can be restricted to an organization or a folder. That bounds what the AI can see. It does not tell you whether what is retrieved is true, which is the whole subject of why found does not mean true.
What you can do on your side
Plenty of gains come without any sophisticated tooling, just from content hygiene:
- Sort: one topic, one scope. Mixing two clients in the same space manufactures confusion.
- Date: put the date in the text itself, not only in the file name.
- Replace instead of adding: when one decision replaces another, mark the old one as replaced instead of leaving both at the same level.
- Name things exactly: write the client name, the reference, the version number. Exact words help the lexical side.
- Delete near-duplicates: keeping ten copies of a document guarantees nine of them will outrank something else.
- One idea per note: a passage that mixes three topics looks a little like everything and answers nothing well.
Current limits
Nawame does not solve these problems. Here is what remains, stated plainly.
- Closeness of meaning is not identity: a connection is a lead to check, and Nawame’s results distinguish a “precedent found” from a “possible connection” for that reason.
- A contradiction nobody recorded cannot be flagged.
- A useful item can be missed. No search guarantees it found everything.
- Quality depends on what gets written: a poorly kept memory will give poor results, at large scale as at small.
- A stronger privacy setting can reduce what the server is able to process, and therefore some features.
There is no figure anywhere in this article. A number with no protocol or test set behind it would mislead, and protocols are more useful than scores.
A test to run on your own collection
Before deciding that a search system “works”, test it on your own data, by hand:
- Write about twenty questions whose right answer you know.
- Add questions whose answer changed over time, to see whether the old one comes first.
- Add questions with no answer in the collection, to see whether the system invents something instead of admitting a gap. We go into the idea in testing topics that do not exist.
- For each question, note whether the right passage came back (recall) and how many useless passages came along with it (precision).
- Run it again once the collection has grown a lot.
If results degrade as volume grows, you know where to act: filter, date, replace, deduplicate. We explain how we sort the errors of a memory in how we measure memory errors, and the Lab gathers our methods.