Lab
With and without memory: what an Embedded evaluation measures
Short answer
An AI assistant can know the facts of a situation without knowing the team’s earlier decision. To measure the effect of that missing context, Nawame and Tsuno compared answers to the same business questions using different ways of accessing memory. The results are encouraging, within the boundaries of the experiment.
Compare access to context
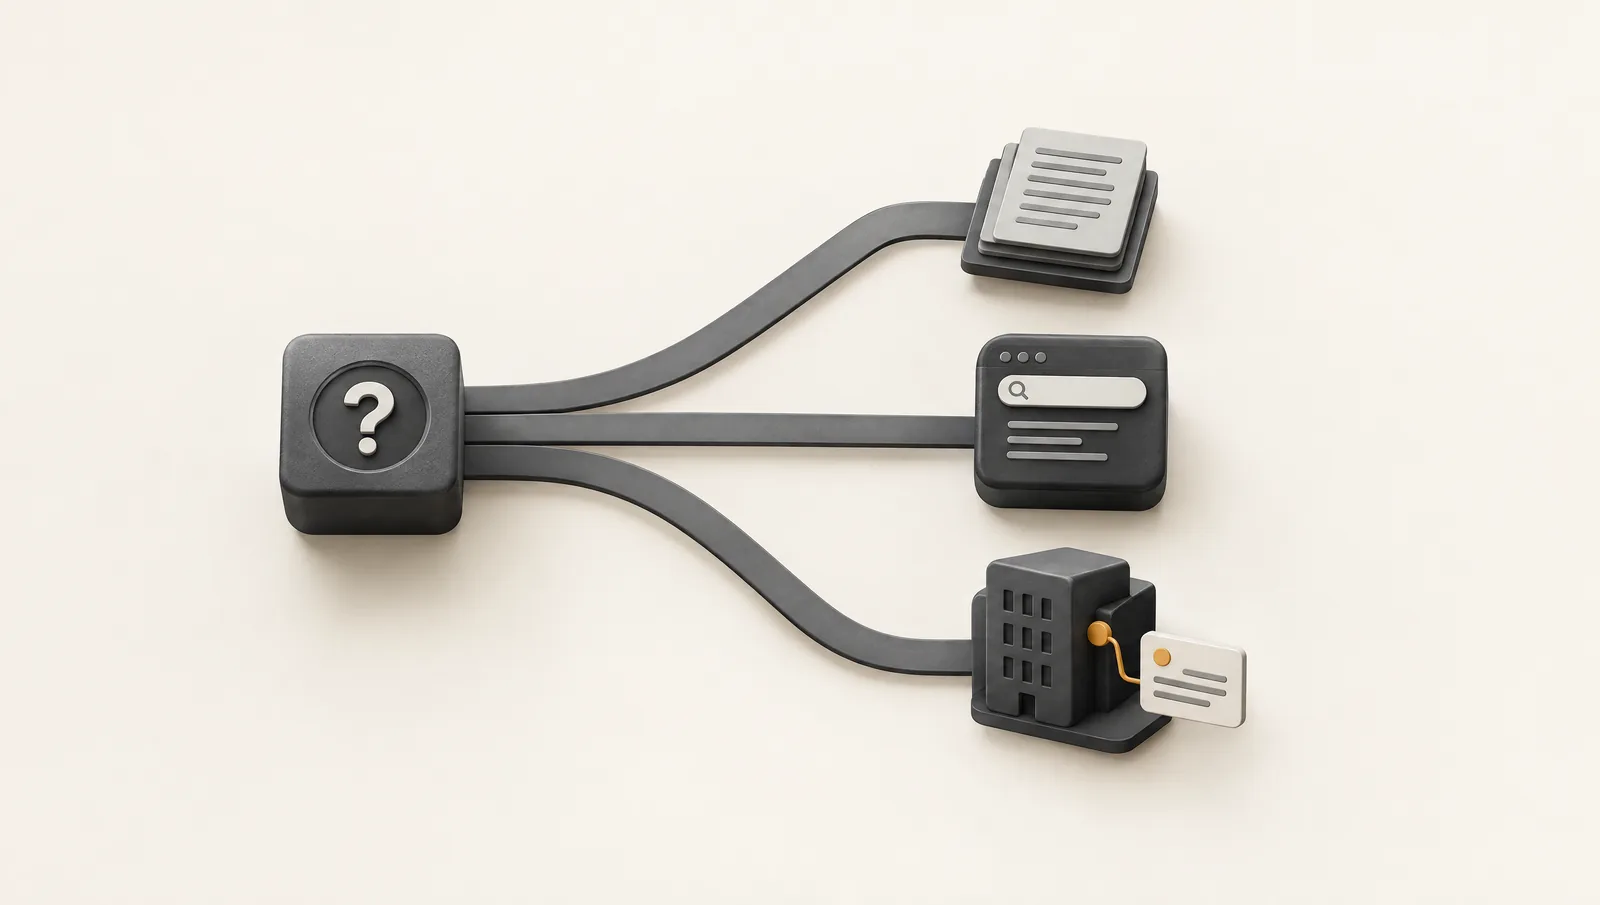
The experiment did not ask which model was the most intelligent. It asked whether retrieving decisions and reasons would improve a business answer.
Three configurations received identical questions. The first had operational facts alone. The second added a full-text search of memory followed by reading the leading results. The third received memory retrieved by business object, including its qualification and dates.
The second configuration matters: this was a comparison against a specific generic search procedure. It does not establish superiority over every search engine, every retrieval-augmented generation system or every retrieval strategy. Changing the comparator could change the size of the benefit.
Results from a fresh dataset
Following an initial campaign, a second campaign used twelve new synthetic scenarios and thirty-six questions. The product code assembled context against a real Nawame test environment, rather than inserting a hand-crafted memory into each question.
Two model families answered at temperature zero. Accuracy measured the presence of expected elements, such as the decision, reason, condition or date required by a question. It was not a claim that every property of every answer was perfect.
| Respondent | Facts alone | Generic search | Object-based retrieval |
|---|---|---|---|
| Qwen3.8-Flash | 35.6% | 63.4% | 100% |
| Llama 3.3 70B | 30.6% | 63.4% | 100% |
Under these conditions, object-linked context substantially improved the recovery of expected decisions. The cases included expired and superseded decisions, as well as absent or inaccessible context.
Test the measurement instrument too
An automatic score can be wrong. In the second campaign, the preregistered requirement for no increase in hallucinations failed for Llama under the raw scoring procedure: two of thirty-six answers were flagged with memory, compared with one without it.
Review found that both flagged memory-assisted answers cited an older decision while explicitly describing it as superseded. Expression matching detected the earlier content without adequately understanding its status. The raw result remains a reported limitation; the audit explains why those flags did not represent actual invention.
The first campaign exposed another measurement problem. The usefulness judge had not received all the dates that a correct answer could legitimately cite. Adding them enabled an exploratory diagnosis. The second campaign then used a fresh dataset and a complete evidence packet. Object-based retrieval scored above generic search in judged usefulness for both models.
What the evidence supports: scope and limits
The work supports a specific hypothesis: retrieving an object’s context, together with its conditions and status, can help an assistant recover a historical decision. It also shows why an evaluation must examine its own instruments.
It does not measure customer time savings, financial returns or fewer operational incidents. The project team wrote the synthetic dataset, and each question received a single measurement per configuration. Independent evaluation and everyday use may reveal other difficulties.
A practical next step is to measure answer quality alongside the human effort required to maintain useful context: whether explanations exist, whether users understand them and whether corrections remain possible. This connects memory attached to business objects with careful collection of human explanations.
Related reading: How to measure whether a memory really avoids rework and How to test an AI memory without cheating on the benchmark.