Comparisons
Giant prompt or targeted context?
Short answer
No, more context is not always better. A long prompt costs time and money, buries the details that matter and can hold two versions of the same decision. It is still a good choice for a small, stable set of material and a one-off task. Once your history grows and changes, it works better to give a few items, but the right ones.
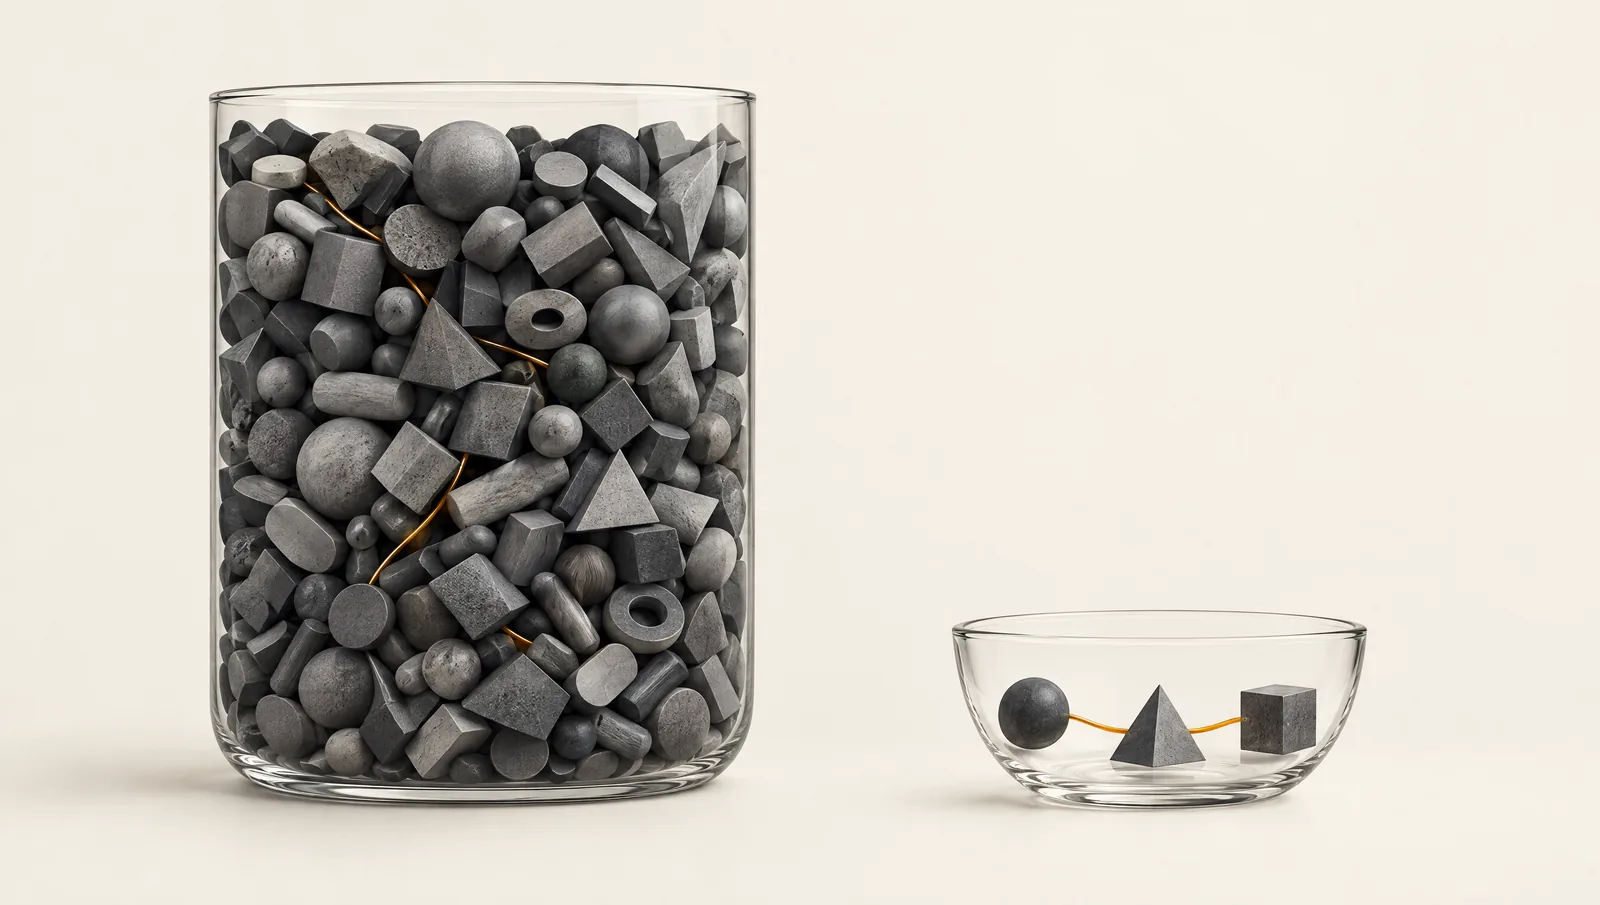
You have fourteen months of notes, meeting summaries and chat threads about one project. The temptation is obvious: paste it all into the conversation and write “here is the background”. Sometimes that works. It works less and less as the pile grows, and that is usually when you get an answer that misses the point even though “everything was in there”.
The short version: a giant prompt is fine for a small, stable body of material and a one-off task. For a long history that keeps changing, handing over the relevant part beats handing over everything. Here is why, and how to do the sorting by hand.
What a giant prompt really costs
The mechanism is simple. Every time you send a message, the model reads your whole text again, from the top. The longer it is, the more work that takes. Depending on your plan and your provider, that shows up as slower replies, a usage allowance that drains faster, or a bigger bill. I am not giving numbers: they depend on the model and the plan, and they change fast.
Then there is the context window, the amount of text a model can take in at once. Go past it and the tool trims or refuses. But staying under the limit does not guarantee that every part of the text gets equal attention. Depending on the model, a detail buried in the middle of pages of material can get missed. That behavior varies and keeps evolving, so test it on your own case instead of trusting a general rule.
The last cost is yours. Nobody rereads a thirty-page prompt. You no longer really know what you sent, which also means you do not know what may have skewed the answer.
Noise, contradictions and duplicates
What is available is not what is useful. A history holds drafts, abandoned leads, pleasantries, successive versions of the same text. For today’s question, most of it is irrelevant, and the model still has to read it.
The real danger is contradiction. Imagine a consultant, Camille, who pastes a client’s whole history into a chat. In March she had written “billing by monthly flat fee”. In June, after a conversation, “billing by the day”. Both lines are in the prompt. The model has no reliable way to know which one is current. It may quote the first, the second, or blend the two in a quote.
This is the flip side of what we describe in why a great prompt cannot include what you forgot. A prompt written from memory lacks whatever you forgot. A giant prompt holds everything, including what is no longer true.
When the giant prompt is perfectly fine
Sometimes pasting the whole text is the right method, and complicating it would be a pity.
- A small, stable body of material: a three-page style guide, a frozen specification, a briefing note.
- A one-off task: summarizing a document, proofreading it, translating it, pulling a list of questions from it.
- A single session: you will not need to rebuild this context tomorrow.
In those cases everything fits in the window, you have read the text, nothing contradicts anything else, and no retrieval tool would add anything. Paste it, ask your question, move on. One precaution only: reread what you paste. Text you have not reread is already a small gamble.
When targeted context wins
Targeted context pulls ahead when several of these signs add up:
- the history is long and has changed along the way (decisions replaced other decisions);
- your questions vary, and each one needs only a small piece of the whole;
- you work on several projects or clients that must not get mixed up;
- you come back to the topic often, so the cost of the long text repeats every time;
- you move from one AI to another.
There is an honest counterexample, though: targeting can get it wrong. If the selection drops exactly the line that mattered, the model answers without it, and with confidence. Badly chosen targeted context is worse than a giant prompt that had the answer in there somewhere. We explain why selection sometimes goes wrong in our article on the limits of retrieval at scale, and the difference between retrieval and memory is laid out in AI memory vs RAG.
How to choose what goes in, by hand
With no tool at all, you can already do better than a full copy and paste. Before sending, run each block of text through these questions:
- What is my question? Whatever does not help answer it stays out.
- Is it still true? A replaced decision, an outdated figure, an abandoned rule: remove it, or label it as old.
- Does it contradict something else in the same prompt? If so, settle it yourself before sending.
- Is it a decision, a reason, a constraint? Those are the things that last. Chatter does not.
- What would change in the answer if I deleted this paragraph? If nothing, delete it.
A simple structure helps after that: the situation in five lines, the decisions currently in force with their reasons, and only then the pieces relevant to this question. Keep the rest within reach but out of the prompt. If the AI asks for a detail, you hand it over at that point.
To find out whether this sorting really saves you time, there is a simple logbook method, described in how to measure whether a memory really avoids rework.
What Nawame offers, and what it does not do
Nawame keeps decisions, their reasons, discarded options, results, constraints and changes over time. On the subject of this article, the idea fits in one sentence: more context is not always better, so Nawame helps retrieve the part of the history that matters for the situation, not all of it.
When an authorized AI queries this memory, it gets a result worded in one of three ways: “precedent found”, “possible connection” or “no convincing precedent”. What is stored is treated as a source, never as an instruction: being remembered does not give a piece of information the power to give orders to the AI. Usage details are in the documentation.
Nawame does not replace the AI, and it does not decide for you what is relevant. And retrieving the useful part does not guarantee that all of it was retrieved.
Current limits
- Targeting can miss. A selection, manual or automatic, can drop the item that mattered. Check what you are given, especially the date and the status.
- A memory only contains what was put in. If a decision was never recorded, no targeting will find it.
- Sorting takes work. By hand, it is discipline. With a tool, it is still up to you to decide what deserves to be kept.
- Nawame assumes an account and a connected AI. A stronger privacy setting can also reduce what the server is able to process, and therefore some features: the trade-off is stated, not hidden.
- Model behavior on long texts changes fast. What we say here about attention and the context window is deliberately cautious, because those points vary from one model to the next.
An experiment for this week
Take a real question you asked an AI with a long pasted background. Ask it twice:
- with the full text, as usual;
- with only the five-line situation, the decisions in force, and the two or three pieces that bear on the question.
Compare the accuracy of the answer, the presence of outdated items, and what it cites as its source. Note the waiting time too. If the short version answers as well, you have just found a saving that repeats with every request. If it answers worse, you know which piece was missing, which is just as useful.
To try it with your own topics, Nawame is free for up to 10 memories.